When Algorithms Say Go and the Body Says No?
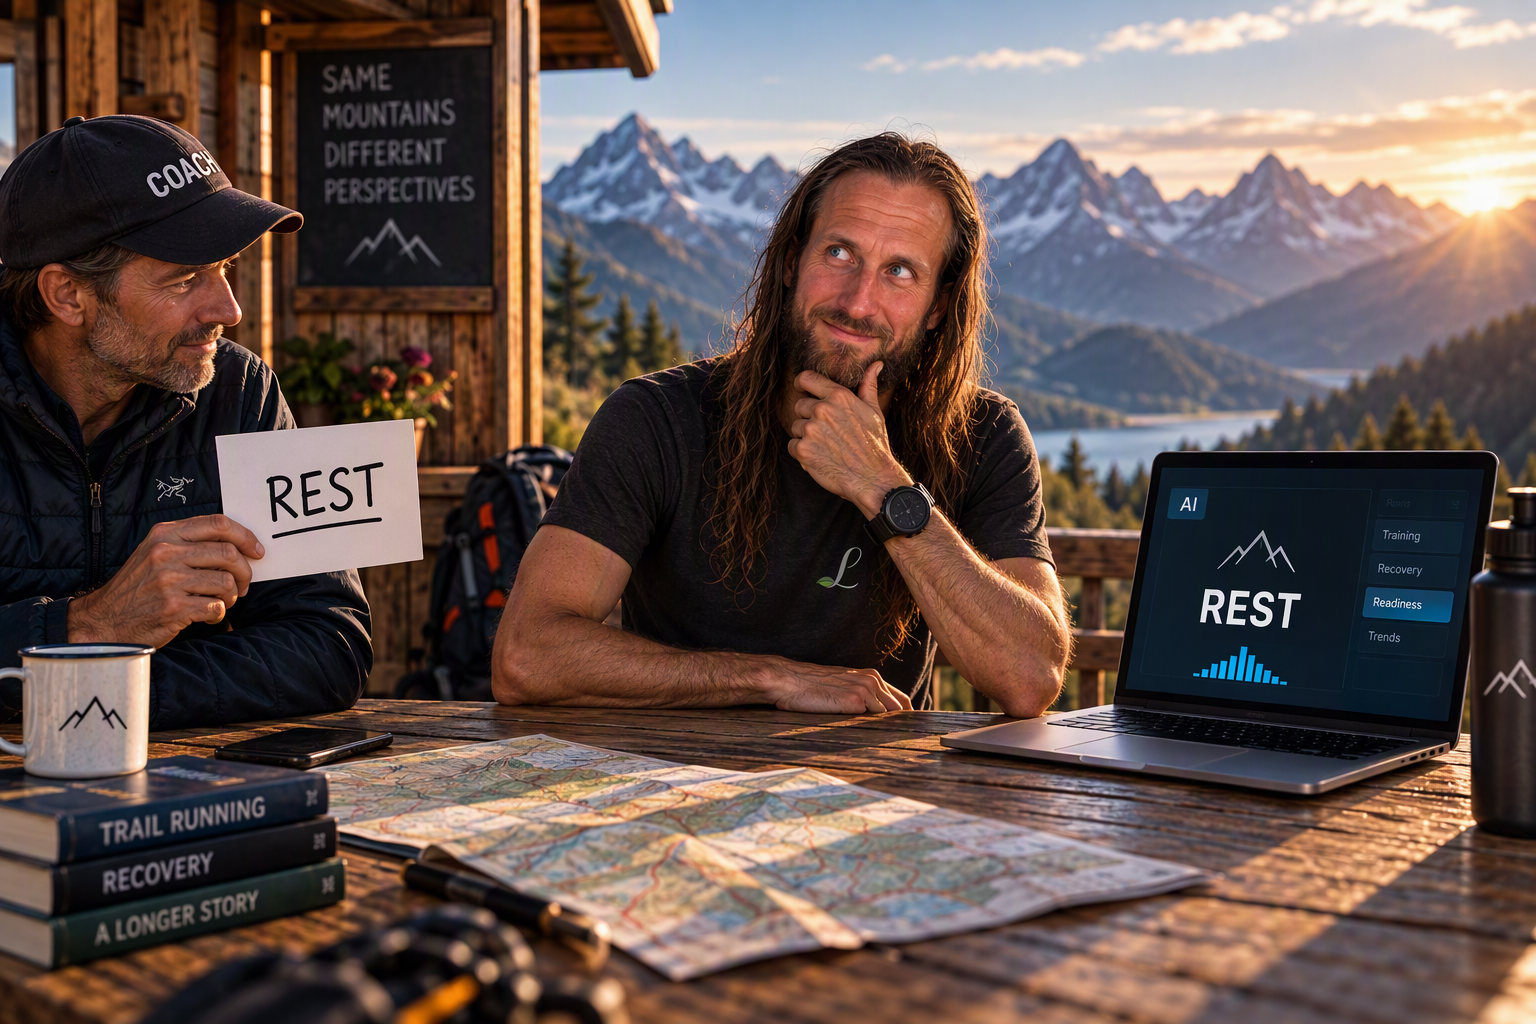
The advice may be identical. Does it matter whether we believe it came from a coach or an AI?
A runner receives a simple recommendation: reduce your training load for the next seven days. It could come from an experienced coach. It could come from an advanced AI system. It could come from a basic programme that applies standard training rules. The words remain the same. Would the runner respond in the same way?
Probably not. One athlete may trust the human coach because the coach knows their history. Another may consider the AI more objective. A third may dismiss automated advice as generic. The advice has not changed. Its perceived authority has.
When the device becomes an adviser
Running technology once recorded what the body had done. It measured pace, distance, heart rate, elevation and cadence. It created a second version of the run, the data double I wrote about in When Garmin Starts Telling the Story. The athlete ran through the world. The device produced a record of that movement.
Technology now does more than record. It interprets data, estimates readiness and recommends training. It tells the athlete when to push and when to recover. In my last post I asked whether such a system can read the body. This time I want to ask what happens when it starts to advise it.
A heart-rate value is one thing. The statement “Your body is ready for high-intensity training” is something else. The second statement turns data into advice. It also turns advice into a story about the body. The athlete may begin to ask the system how they feel before asking themselves.
Does the source matter?
Vodrahalli et al.[1] tested a version of this question. They asked how people respond to the same advice when only its stated source changes: an AI algorithm or a group of peers. More than 1,100 crowdworkers in the US, the UK and Asia judged paintings, photographs of cities, sarcasm in text and income levels from census data. In both conditions the advice was identical and described as 80 per cent accurate.
The source did matter, but only at the door. Participants’ prior beliefs decided whether they used the advice at all. Those who thought AI was better at the task were more likely to act on AI-labelled advice. For sarcasm, participants on average favoured the human, and the effect reversed. The differences were modest, roughly six percentage points in how often people changed their answer. Once people decided to use the advice, there was no significant difference in how they incorporated it, whatever the label.
The authors call this an activation-integration model. First, people decide whether to use the advice. Then they decide how far to adjust their judgement. For coaching, the source may determine whether advice gets through the door. It may matter less once the athlete has decided to listen.
Some caution is needed before we carry this over to running. The study did not examine athletes or training decisions. The tasks were low stakes. Nobody’s body was on the line, and the “human” was an anonymous group of peers, not a coach who knows you. Still, it is a useful starting point. Is reading a tired body more like spotting sarcasm, where people leaned towards the human, or more like recognising a city skyline, where they leaned towards the machine? I suspect runners will disagree.
The authors also tried a more realistic setting. They trained an AI model to advise 37 dermatologists on whether to biopsy a skin lesion. Here the label made no visible difference. The dermatologists acted on human and AI advice about equally often, and both improved accuracy by a similar amount. The authors flag this as a possible limitation, because in real practice human advice usually comes from a known and trusted colleague. In that small sample, more years of clinical experience also meant less willingness to act on advice from either source.
That reminds me of something I am debating in my thesis. Endurance athletes seem to trust advice from their peers, their social in-group, more than medical advice, as I touched on in The Disciplined Body. That may be as misguided as any other preference for what we want to hear. It may also be a way of not losing ourselves, who we are, through an injury. But that is a discussion for another day.
The study opens with medicine, where caution about AI remains high and a human in the loop is the safeguard. My impression is that this caution is fading faster in sport. The human in the loop may even become obsolete, and as I argued last week, there is never a shortage of influencers ready to tell you what is right for YOU.
The authority of AI
AI is often perceived as objective. It can process large amounts of information. It does not become tired. It does not forget yesterday’s numbers. It appears less influenced by emotion. These qualities can make its recommendations seem neutral. But the system itself is not neutral.
Its advice depends on the data it receives. It depends on the people represented in its training data, on which variables are measured and which are ignored, and on the assumptions used to interpret them. The output may look precise. That does not make it complete. Still, precision can carry authority. In the study, more confident-looking advice was more likely to prompt a change of answer.
A coach might say: “You seem tired. I think you should reduce your training.” An AI system might say: “Your recovery pattern indicates an elevated risk of maladaptation. Reduce your training load by 23 per cent.” The second recommendation sounds more scientific. It may also feel more personal because it appears to be based on the athlete’s own data.
But the athlete may not know how the recommendation was produced. The appearance of precision can become a substitute for understanding. The authors name the black-box nature of AI as one of the main barriers to trust. I am not claiming we know what goes on inside a coach either. A coach compares you with other athletes, with themselves, sometimes with the runner they wish you to be, like the parent who wants you to achieve what they never could. Bodies differ widely, so perhaps no algorithm, human-made or AI-generated, will ever be perfect. Perhaps the smartest combination is to trust both, with a pinch of self-determination.
The advice we want to hear
Athletes do not assess advice neutrally. As I wrote last week, we normalise fatigue when the race is close. A high readiness score can provide permission to train. A low score can be dismissed because the device does not understand how we feel. The same athlete may treat the same system as authoritative one day and irrelevant the next. Much depends on what the system says.
Advice to train harder may be welcomed. Advice to rest may be questioned. This is not unique to AI. Athletes respond in the same way to coaches, physiotherapists and doctors. AI adds another source of authority to this negotiation. The athlete may follow the system not because it is more accurate, but because its recommendation appears objective.
When the numbers become the feeling
Self-tracking does more than describe the body. It can change how the body appears to the athlete. A runner wakes feeling rested. They check a poor recovery score. Fatigue becomes more noticeable. Another runner wakes feeling depleted. Their readiness score is high. The fatigue begins to feel less important.
The data do not merely sit beside bodily experience. They help shape its interpretation. This does not mean the sensations are imaginary. What we notice can be shaped by what we expect to find. The runners in Lev and Landgren’s study felt free without their watches, but also uncertain of their own abilities, as I described in “If It Isn’t on Strava, Did It Happen?”. The quiet certainty of the device had become part of how they judged a run.
AI strengthens this effect because it interprets the numbers for us. The system does not simply show a low heart-rate variability score. It explains what the score means. It may then recommend how to act. The data double has gained a voice.
Outsourcing bodily interpretation
This creates a risk. If athletes repeatedly defer to algorithmic guidance, they may become less confident in their own sensations. A readiness score may begin to feel more authoritative than the legs it claims to describe.
Vodrahalli et al. offer a clue about who is most exposed. Participants who were unsure of their first answer were more likely to change it after advice. Those who were sure barely moved. On the trail, that might mean the ambiguous niggle is where we defer most easily. I would not push this too far, because the tasks were paintings, not pain. But it is a pattern worth testing.
The opposite is also possible. Some athletes habitually ignore fatigue. For them, an external reference point could restore attention to signals they have learned to suppress. Technology could weaken embodied awareness. It could also support it. The result depends on how the advice is produced, presented and used.
The ultrarunner’s paradox
This tension is sharpest in ultrarunning. An ultrarunner may need to continue while tired, uncomfortable, sleep-deprived and uncertain about pain. That ability can be admirable. It can also be dangerous. The athlete most capable of enduring distress may be the least willing to notice when that distress has changed.
Judgement can also deteriorate during a long event. Fatigue makes interpretation harder at the moment when interpretation matters most. A runner may believe they know their body. They may also be cognitively impaired and deeply invested in finishing.
An AI system might provide an external reference point. It could pick up changes in pace, movement, heart rate or the athlete’s reported state, and recommend slowing down or stopping. Would the runner listen? That depends on how much authority they grant the system, and on whether the recommendation supports or obstructs their goal. The system could send a warning that the athlete ignores. It could also give the reassurance the athlete desperately wants to hear. And as I noted last week, the data on ultrarunners is thin. A system can only work with what it has learned from.
When nobody could advise me
Two years ago, I ended up without advice from doctors and peers alike. Not by choice. Nobody knew what the parasite was or what it was doing inside me, and it set off inflammatory processes throughout my whole body (read more here). With no diagnosis, there was little to follow. So, I relied on myself. I started lifting and running again, slowly and steadily building up, and I leaned on 30 years of training experience. No AI would have had that kind of data: three decades of how my body responds, most of it never recorded. The return-to-play tools in the review I discussed last week compare recovery with a pre-injury baseline, but a baseline means little when nobody can name the cause. And no doctor can write a return-to-play script without knowing what stopped me in the first place.
This is not a case for trusting only your body. Doctors are there for a reason, and in most situations, they should be the first call. Mine was an exception, because nobody could say what was happening inside me. It worked out. It could have gone differently, and I cannot tell from the inside which it would have been. That is the uncomfortable part. In Vodrahalli et al.’s dermatology test, the more experienced clinicians were less likely to heed advice. Sometimes that is wisdom. Sometimes it is stubbornness with a good track record.
The experiment I would like to run
Vodrahalli et al. never tested athletes. It would be interesting to do so, and to measure performance, not only trust. Imagine four groups of runners. Three receive the same recommendation: reduce your training load for the next seven days. The first group is told it came from an experienced human coach. The second is told it came from an advanced AI system. The third is told it came from a basic automated programme. The fourth receives no advice at all. The recommendation stays the same. Only its stated source changes.
Would the groups differ in trust? In adherence? In performance? Would the advice change how they interpret fatigue during the following week? The direction of the advice may matter too. Athletes may respond differently to advice to train harder than to advice to rest. Their experience with technology, their relationship with coaches and previous injury could all shift the result. I suspect amateurs and elites would differ, but that is a discussion for another time, or perhaps a longer-term research project.
These questions are not only about whether AI gives good advice. They concern what happens when athletes believe AI has the authority to interpret their bodies.
Such a study would raise ethical issues. If participants are told advice came from AI when it did not, the study involves deception. That would require clear justification, informed consent that allows for withheld information, and full debriefing. Adding groups that receive deliberately poor advice would raise welfare questions too, since a bad training recommendation is not a bad guess about a painting. Vodrahalli et al. make a related point. If the way AI advice is presented can shape how people use it, miscalibrated beliefs could cause harm, and the aim must be to avoid over-trusting an AI agent.
Beyond body versus algorithm
It would be satisfying to choose a winner. Trust the body. Trust the coach. Trust the data. None of these instructions is enough. Last week I described four ways of knowing the body, and none had automatic authority. This study adds a further twist: how much authority a voice seems to have may count as much as what it says.
The question is not whether athletes should trust their bodies instead of algorithms. A better question is how AI can support bodily interpretation without replacing it. The algorithm may sometimes see what the athlete cannot. The athlete may sometimes feel what the algorithm cannot see. The coach may sometimes recognise the conflict between them.
The future of AI coaching may depend less on whether a machine can know the body. It may depend more on whether it helps athletes know their own bodies better.
Written by Ingo@Lozania-Lifestyle.de
----
[1] Vodrahalli, K., Daneshjou, R., Gerstenberg, T., & Zou, J. (2022). Do humans trust advice more if it comes from AI? An analysis of human-AI interactions. In Proceedings of the 2022 AAAI/ACM Conference on AI, Ethics, and Society (AIES ’22) (pp. 763–777). ACM. https://doi.org/10.1145/3514094.3534150